- Published on
Z.ai GLM-Legal: Why #1 on Harvey LAB Still Means 19.2% All-Pass
- Authors
- Name
- Hoang Nguyen
👤 1. Who Is Involved & Impacted?
- Creator: Z.ai (makers of the
GLMseries and AutoClaw), releasing the domain-specializedGLM-Legalagent model. - Models Benchmarked: Evaluated against
GLM-5.3-Flash,Kimi K3,Claude Fable 5, andGPT-6 AstraacrossHarvey LAB,LegalBench, andPLawBench. - Community: Sparked 676 points and 371 comments on Hacker News as lawyers and engineers contrasted high academic scores (
86.2%) against strict end-to-end workflow grading (19.2%).
📦 2. What Is GLM-Legal?
GLM-Legal is an agentic legal model built for multi-document deal rooms, statutory cross-checking, and contract drafting inside AutoClaw:
- Harvey’s Legal Agent Benchmark (
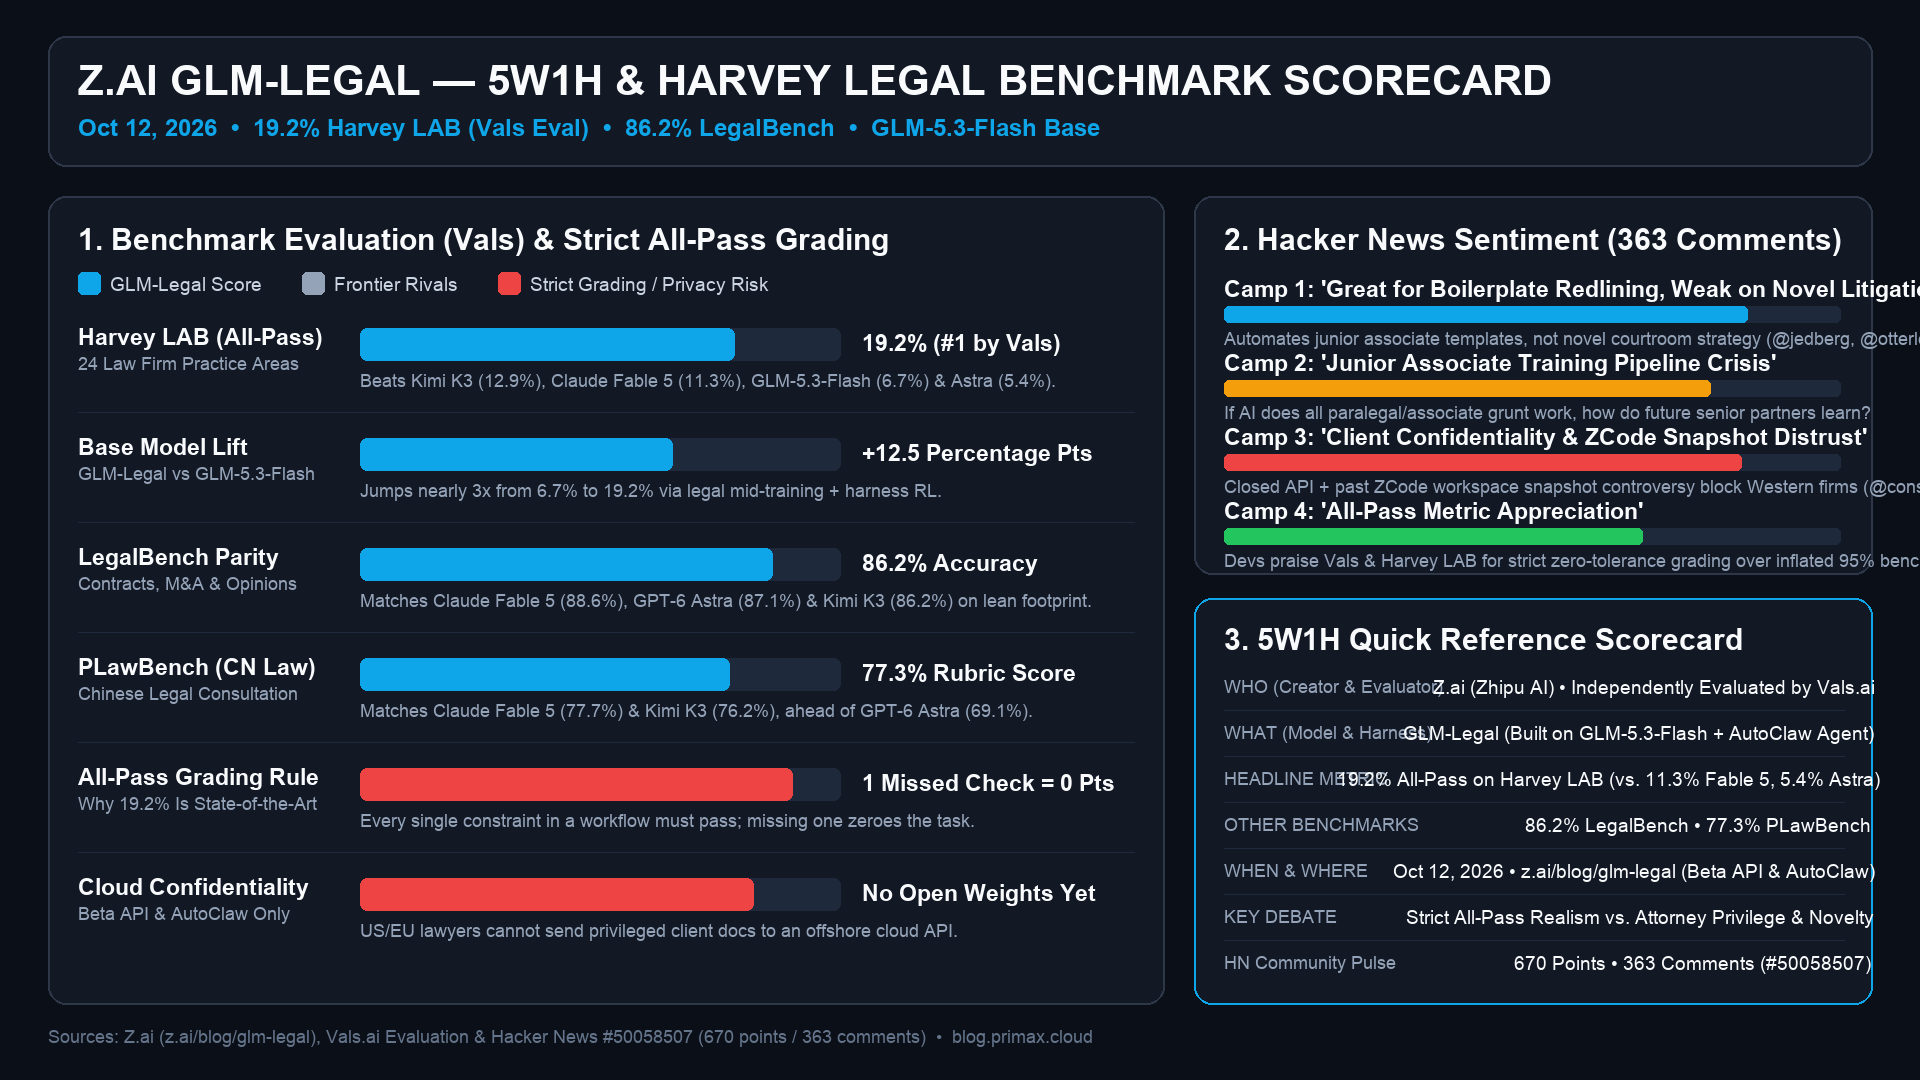
Harvey LAB— Strict All-Pass): Scores19.2%(#1 overall, nearly triplingGLM-5.3-Flashat6.7%, and beatingKimi K3(12.9%),Claude Fable 5(11.3%), andGPT-6 Astra(5.4%)). LegalBench(Academic Legal Reasoning): Scores86.2%, matchingKimi K3(86.2%) and trailingClaude Fable 5(88.6%) andGPT-6 Astra(87.1%) on a much smaller parameter footprint.PLawBench(Localized Legal Practice): Scores77.3%, virtually tied withGPT-6 Astra(77.7%) and ahead ofClaude Fable 5(76.2%).
📅 3. When & Where?
- When: Released on October 12, 2026.
- Where: Technical report at z.ai/blog/glm-legal, live in AutoClaw, and discussed on Hacker News (#50058507).
🎯 4. Why Did the 19.2% Score Go Viral on HN?
- Strict All-Pass Grading: Unlike multiple-choice evals, Harvey LAB grades real law-firm workflows across 24 practice areas where a model gets credit (
1) only if 100% of rubric items pass across every file. - 19.2% All-Pass = 80.8% Flawed: While domain RL nearly tripled the base model's pass rate (
6.7% -> 19.2%), HN spotlighted the reality check: even the #1 legal agent on Earth fails strict lawyer-grade verification80.8%of the time. - Verification Asymmetry: In code, a bug fails the compiler or test suite; in a 150-page M&A contract, a single hallucinated carve-out creates silent malpractice liability—requiring human attorneys to review every line anyway.
⚙️ 5. Benchmark Comparison & Community Reaction
| Benchmark | Grading Regime | GLM-Legal | GLM-5.3-Flash | Kimi K3 | Claude Fable 5 | GPT-6 Astra |
|---|---|---|---|---|---|---|
Harvey LAB | Strict All-Pass (24 areas) | 19.2% (#1) | 6.7% | 12.9% | 11.3% | 5.4% |
LegalBench | Academic legal reasoning | 86.2% | 83.9% | 86.2% | 88.6% | 87.1% |
PLawBench | Localized drafting rubrics | 77.3% | 73.8% | 76.2% | 76.2% | 77.7% |
- Respect for Honest Benchmarks: Commenters praised Z.ai for publishing a brutal benchmark where top models score
5.4%–19.2%instead of cherry-picking 95%+ saturated evals. - Why Generalist Models Failed
Harvey LAB: Generalist models (GPT-6 Astraat5.4%) tend to paraphrase clauses rather than preserving exact statutory phrasing across 20+ documents.
✅ CONCLUSION
Z.ai proved that lean domain-specific training (19.2%) can beat giant generalist models (Claude Fable 5 at 11.3%, GPT-6 Astra at 5.4%) on real legal workflows—while the 80.8% strict failure rate confirms that legal AI remains a paralegal copilot requiring 100% human audit.