- Published on
Claude Haiku 5.5 in 1 Page — 5W1H Breakdown & Benchmark Scorecard
- Authors
- Name
- Hoang Nguyen
Released on October 7, 2026, Claude Haiku 5.5 (claude-haiku-5-5) brings the full Claude 5.5 architecture—1M context, 128K output, and adaptive thinking—to the bottom of the price ladder at 0.50 per 1M tokens (for prompts ≤100K). Here is the complete 1-page 5W1H engineering and benchmark brief.
1. Executive Summary: Claude Haiku 5.5 in 5W1H
| Dimension | Concise Breakdown |
|---|---|
| WHAT | Anthropic's fastest, cheapest small model (claude-haiku-5-5), upgraded with a 1M-token context window, 128K max output, adaptive thinking (effort: low → max), and native Computer & Browser Use. |
| WHY | Delivers a 4.6x leap in desktop automation (72.4% vs. 15.7% on OSWorld 2.1), beats OpenAI's GPT-6 Luna on every published benchmark, and cuts per-token list prices by 90% (≤100K prompts) or ~75% on average in production. |
| WHO | AI / Platform Engineers & SREs running high-volume classification, document extraction, live customer support, browser automation, and worker subagents orchestrated by Sonnet 5.5 or Opus 5.5. |
| WHERE | Generally available on Claude API (claude-haiku-5-5), AWS Bedrock (anthropic.claude-haiku-5-5), Google Cloud Vertex AI, and Microsoft Foundry. |
| WHEN | Adopt immediately for high-volume, well-scoped pipelines and subagent tasks (guaranteed active until at least Oct 7, 2027). Keep Sonnet 5.5 for complex multi-step CLI coding. |
| HOW | Call via the updated Claude SDKs using output_config={"effort": "low"|"medium"|"high"} after removing legacy budget_tokens, custom sampling parameters, and assistant prefills. |
2. WHY: Official & Real-World Benchmark Scorecard
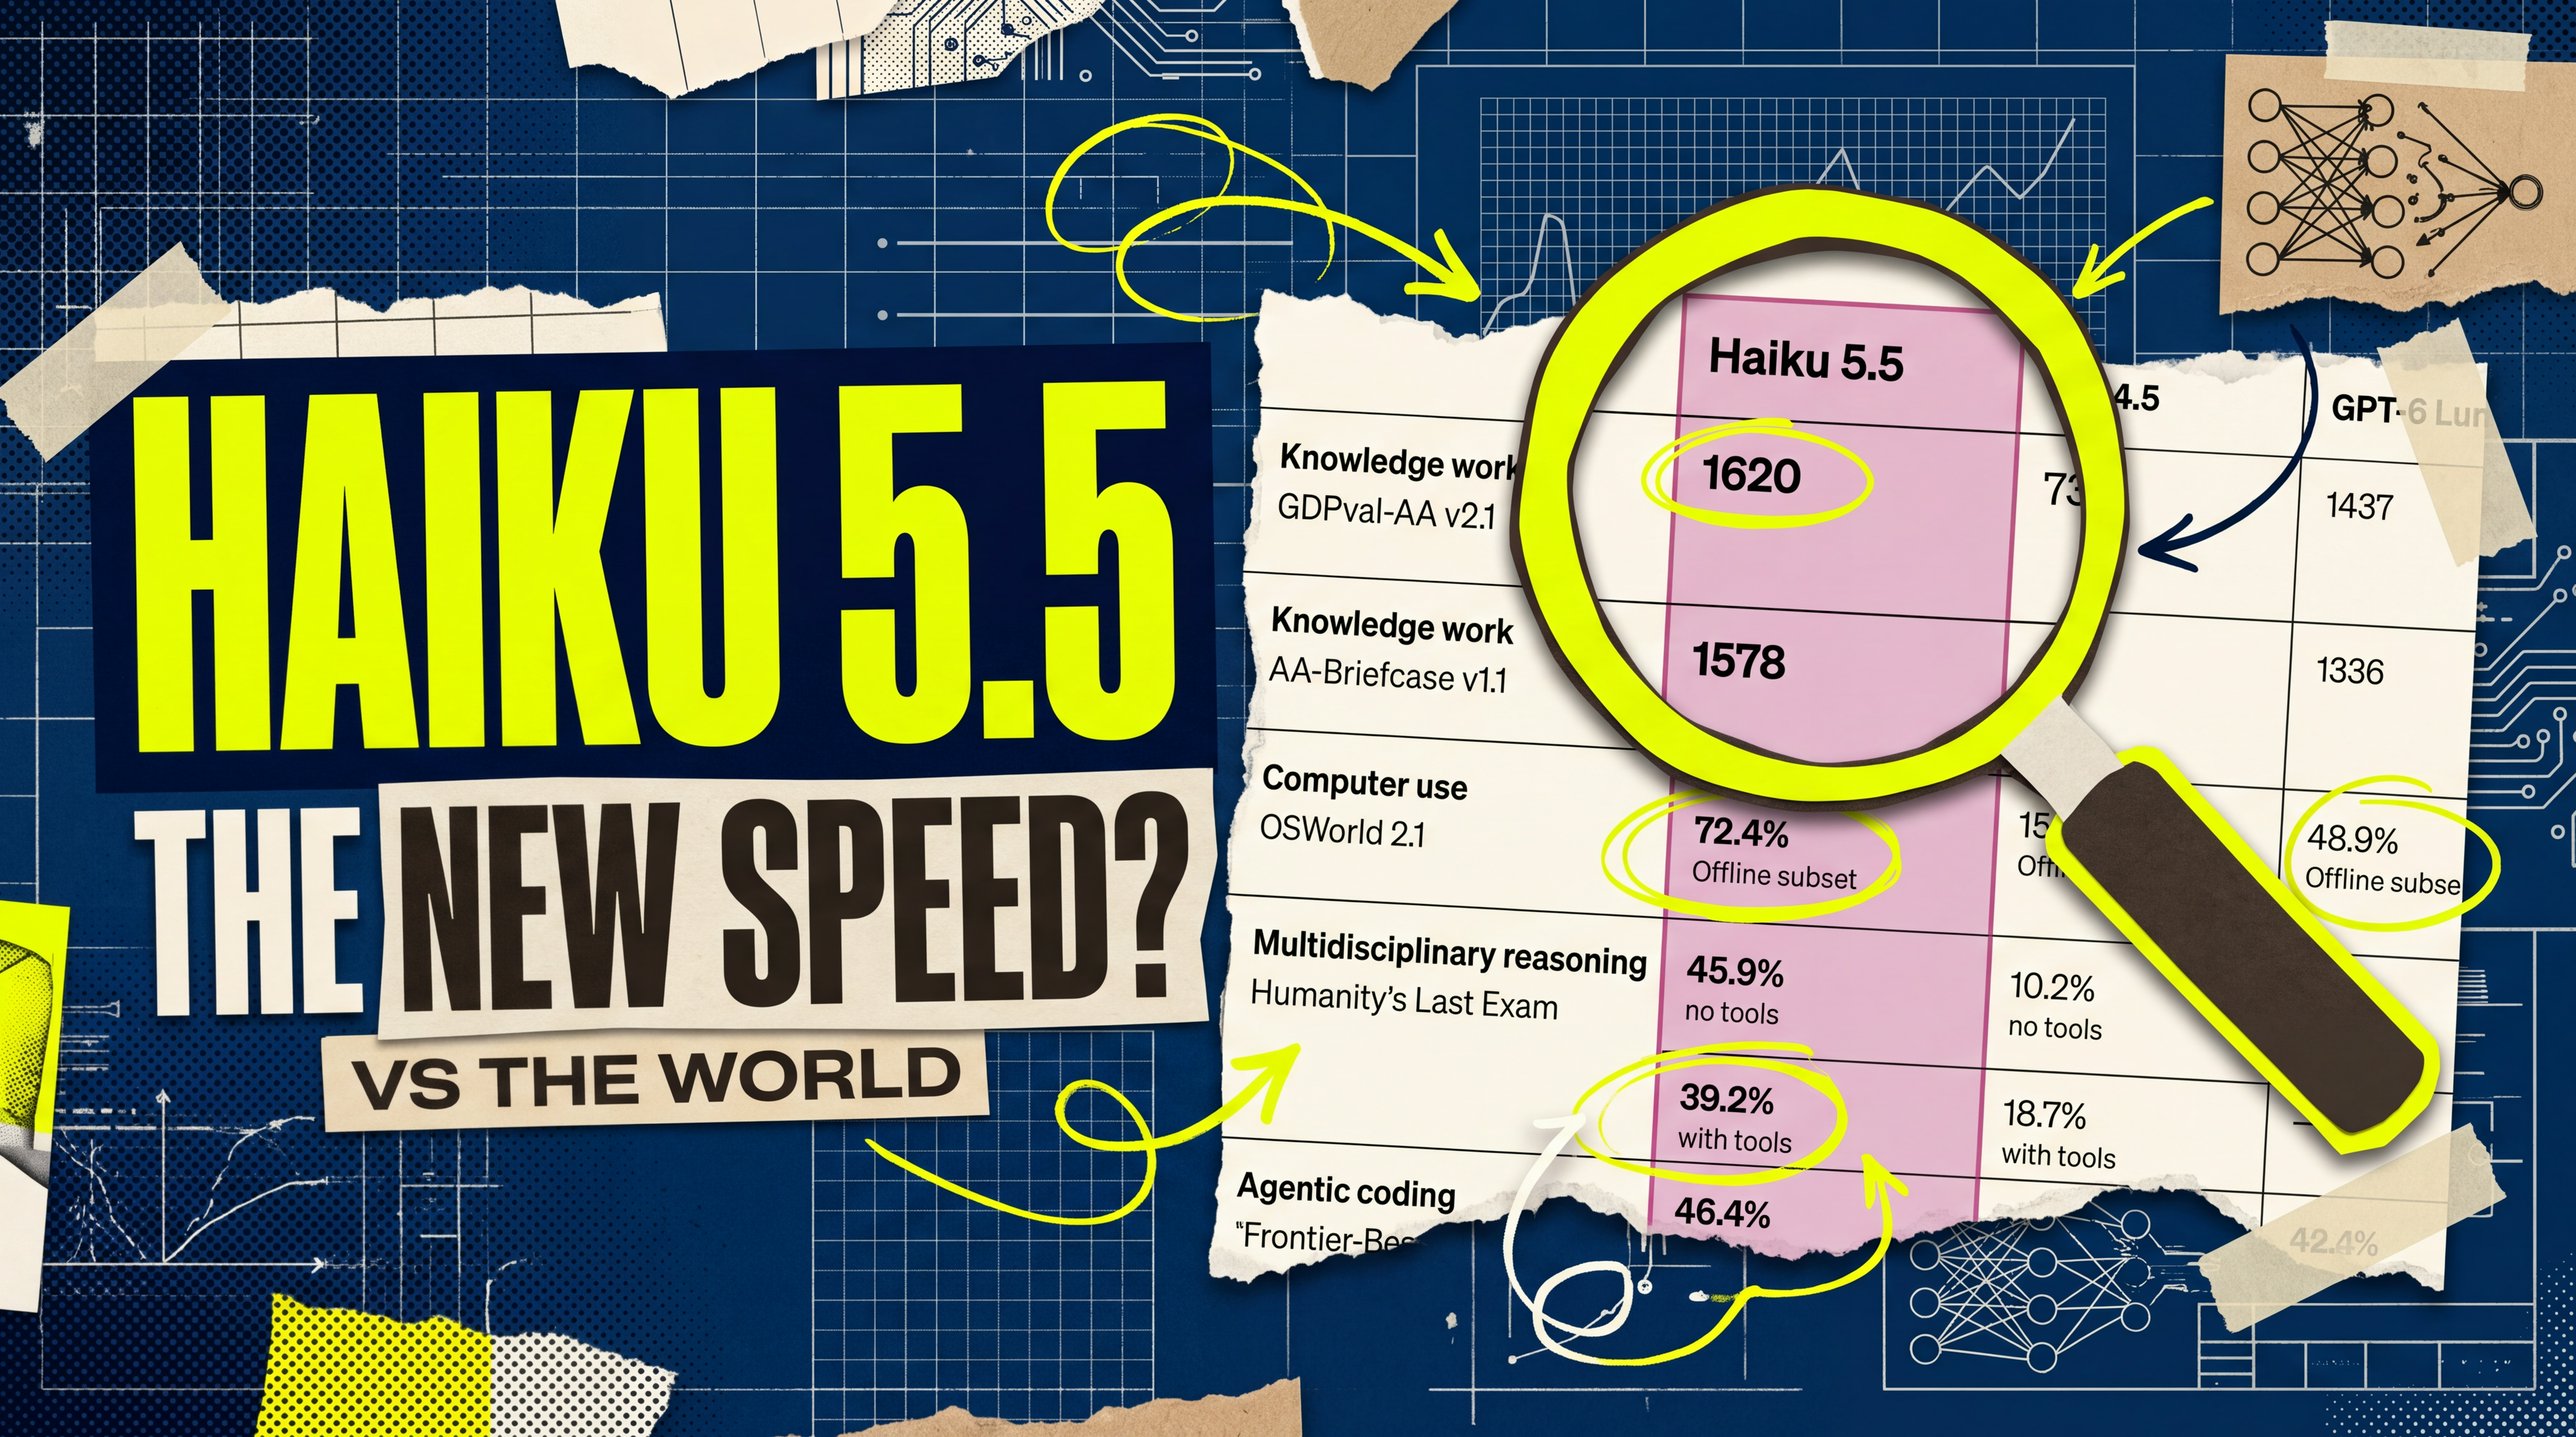
Haiku 5.5 transitions from a text-only lightweight classifier into a capable agentic worker—outperforming Haiku 4.5 by massive margins and leading OpenAI GPT-6 Luna across every shared evaluation, while trailing Sonnet 5.5 on complex coding.
Head-to-Head Model Benchmarks
| Category | Benchmark | Claude Haiku 5.5 | Claude Haiku 4.5 | OpenAI GPT-6 Luna | Claude Sonnet 5.5 (Ref) | Haiku 5.5 vs. 4.5 Delta |
|---|---|---|---|---|---|---|
| Knowledge Work | GDPval-AA v2.1 (Elo) | 1,620 | 735 | 1,437 | 1,840 | +120.4% (+885 Elo) |
| Knowledge Work | AA-Briefcase v1.1 (Elo) | 1,578 | 614 | 1,336 | 1,824 | +157.0% (+964 Elo) |
| Computer Use | OSWorld 2.1 (Offline) | 72.4% | 15.7% | 48.9% | 83.9% | +56.7 pts (4.6x) |
| Agentic Coding | Terminal-Bench 4.0 | 39.2% | 0.0% | 16.4% | 70.6% | 0% → 39.2% |
| Agentic Coding | FrontierCode 1.1 (Main) | 46.4% | — | 42.4% | 52.1% | Beats GPT-6 Luna (+4 pts) |
| Expert Reasoning | Humanity's Last Exam (No tools) | 45.9% | 10.2% | — | 56.9% | +35.7 pts (4.5x) |
| Expert Reasoning | Humanity's Last Exam (With tools) | 57.4% | 18.7% | — | 64.5% | +38.7 pts (3.1x) |
| Visual Reasoning | Chartography (No tools) | 46.4% | 6.4% | 29.1% | 61.6% | +40.0 pts (7.25x) |
Real-World Production & Hands-On Benchmarks
- DataCamp 24-Invoice Accounts Payable Test: Tested on 24 vendor invoices with policy traps (3% price tolerance, split deliveries, swapped PO digits). Both Haiku 5.5 (
higheffort) and Haiku 4.5 (16Kthinking budget) scored 24/24 (100% accuracy), but Haiku 5.5 used under 25% of the output tokens and cost$0.0098vs.$0.25(~25x cheaper). - Enterprise Production Evaluations:
- HubSpot (CRM Audit): 92.8% average score across 3 runs—fastest completion, highest hit rate, and lowest false-positive rate.
- AlphaSense (8M weekly doc queries): Statistically significant jump from 0.76 → 0.84 over Haiku 4.5.
- Box AI & Asana: +11 points higher accuracy at ~50% latency (Box); 20% lower task latency and up to 2.5x faster inference per agent turn (Asana).
- Cognition (Devin Fusion): Paired as a sidekick to Opus 5.5, holds a 66.2 FrontierCode score while slashing cost and latency.
Pricing & Token Economics (Per 1M Tokens)
| Metric / Rate Tier | Haiku 5.5 (≤100K Prompt) | Haiku 5.5 (>100K Prompt) | Haiku 4.5 | Sonnet 5.5 |
|---|---|---|---|---|
| Input / Output | $0.10 / $0.50 (-90%) | $0.50 / $2.50 (-50%) | $1.00 / $5.00 | $2.00 / $10.00 |
| Cache Read / 5m Write | $0.01 / $0.125 | $0.05 / $0.625 | $0.10 / $1.25 | $0.10 (cut 50%) / $2.50 |
| Context / Max Output | 1M / 128K tokens | 1M / 128K tokens | 200K / 64K tokens | 1M / 128K tokens |
Why "75% cheaper on average" instead of 90%? Two reasons: (1) Haiku 5.5 uses the newer 5.5-family tokenizer, which produces ~30% more tokens for the same text than Haiku 4.5, and (2) prompts over 100K tokens (~10% of historical traffic) pay 5x the base rate (
$0.50/$2.50). Combined with the 50% Batch API discount, high-volume pipelines still see dramatic savings.
3. WHO, WHERE & WHEN: Claude 5.5 Tier & Effort Matrix
All four current Claude models share a 1M context window and 128K max output:
| Model Tier | Input / Output (1M) | Latency & Default Effort | Best Production Use Case |
|---|---|---|---|
| Claude Haiku 5.5 | $0.10 / $0.50 | Fastest (medium) | low: Routing, moderation, tagging.medium/high: Extraction, chart/doc parsing, UI/browser automation, subagents under Sonnet/Opus. |
| Claude Sonnet 5.5 | $2.00 / $10.00 | Fast (high) | Primary coding agents, CLI engineering (70.6% Terminal-Bench), orchestrating Haiku subagents. |
| Claude Opus 5.5 | $4.00 / $20.00 | Moderate (medium) | Deep architectural planning, complex multi-agent orchestration. |
| Claude Fable 5.1 | $10.00 / $50.00 | Slower (high) | Frontier R&D and maximum-difficulty synthesis. |
4. HOW: Minimal Implementation & Breaking Migration Checklist
from anthropic import Anthropic

client = Anthropic()
response = client.messages.create(
    model="claude-haiku-5-5",
    max_tokens=4096,
    output_config={"effort": "low"},  # "low" | "medium" (default) | "high" | "max"
    messages=[{"role": "user", "content": "Extract invoice total and PO number: ..."}],
)
# Adaptive thinking is on by default; filter blocks by type rather than index 0
print(next(b.text for b in response.content if b.type == "text"))
5 Breaking Changes When Migrating from Haiku 4.5
- No
budget_tokens: Manual extended thinking throws an error; switch tooutput_config={"effort": ...}. - No Custom Sampling: Non-default
temperature,top_p, ortop_kvalues return an API error. - No Assistant Prefill: Prefilling assistant messages is no longer supported.
- Read Content by Type: Responses may start with
thinkingblocks—always selectb.type == "text"instead ofresponse.content[0]. - Updated Computer Use Toolset: Requires
computer_toolset_20260801and append-only conversation history (editing prior turns invalidates thinking blocks).